Library / Courses
MIT 6.824: Distributed Systems
Free university course on fault tolerance, replication and consensus with Go labs.
By Robert Morris · MIT · Added 2026-09-11
All content belongs to Robert Morris / MIT. We only link to it and give credit. Report a problem
Learn this course
About 37 min left. Your work is saved as you go.
What you want from this course
MIT teaches this course. Decide how many hours a week you can give it, and book those sessions.
Ideas you will meet
- Distributed Systems
- Consensus, time, failure and the fundamentals of scale-out.
- Replication
- Leader/follower, multi-leader and leaderless replication.
- Consistency Models
- Linearizable, causal and eventual consistency explained.
What we already know about this
Our own lessons on these ideas. Read them here before you start, so it makes sense.
Databases Deep Dive · 12 minReplication topologies and multi-region databasesSingle-leader, multi-leader and leaderless replication, how they handle conflicts and lag, and what changes across regions.Read here
Why replicate
Replication keeps copies of data on several machines for three reasons: availability (survive a node failure), read scaling (serve reads from replicas) and latency (put data near users). The hard part is keeping copies consistent while writes continue. (Basics are in the replication and sharding lesson of the foundations course; this lesson compares the topologies.)
Single-leader (primary and replicas)
One node, the leader (primary or master), accepts writes and ships its changes to followers (replicas), which serve reads.
100%Figure SDA-DDV-04-1 · Single-leader replication · © forcsguy.com
- Synchronous replication waits for a follower before acknowledging: safer, slower, and a stalled follower can block writes. Asynchronous is faster but a failover can lose the latest writes. A common compromise: one synchronous follower, others asynchronous.
- Failover must detect failure, choose the most up-to-date replica, redirect clients and ensure the old leader does not come back believing it still leads (split brain).
- Replication lag causes stale reads. Techniques: read-your-writes (route a user's reads to the leader shortly after they write), monotonic reads (keep a user on one replica), and checking replica position.
Multi-leader
Several nodes accept writes (often one per region) and replicate to each other. Benefits: local write latency and continued operation if a region is cut off. Cost: write conflicts.
Conflict handling options:
- Avoid them: route all writes for one record to one leader (for example by user or region).
- Last write wins by timestamp: simple, but silently drops one of two concurrent updates and depends on clocks.
- Merge values (union of sets, counters) using mergeable data types (CRDTs; see the collaborative editing lesson).
- Custom resolution in application code, or ask the user.
Multi-leader also appears in offline-capable apps (each device is a leader) and collaborative editing.
Before: single leader
100%After: multi-leader across regions
100%What changed
- Users in each region write to a nearby database
- Concurrent edits to the same row need conflict handling
- More moving parts to run and monitor
Leaderless (Dynamo-style)
Any replica accepts writes; clients write to several replicas and read from several, using quorums (
W + R > N) to get fresh data (see the key-value store lesson). Background anti-entropy and read repair fix stale copies; versions or vector clocks detect conflicts. It favours availability and is typical of Cassandra and DynamoDB-style stores.100%Figure SDA-DDV-04-2 · Choosing a replication model · © forcsguy.com
Multi-region designs
- Active-passive: one region serves writes; another is a warm standby. Simple; failover loses a little data (the replication lag) and takes minutes.
- Active-active: several regions serve traffic. Requires either partitioning data by home region (each record has one home, cross-region reads are replicas) or true multi-leader conflict handling.
- Global databases use consensus across regions (see the consensus lesson) for strong consistency at the cost of cross-region write latency; some offer tunable consistency per query.
- Latency numbers matter: a cross-ocean round trip is around 100 ms or more, so synchronous cross-region replication adds that to every write.
- Data residency laws may require keeping certain users' data in a region.
Partitioning and replication together
Real systems shard data into partitions and replicate each partition (a leader per partition spreads write load across nodes). Rebalancing, hot partitions and cross-partition transactions are the new problems (see sharding and the consistent-hashing lesson).
Master/slave naming
You will see "master/slave", "primary/replica" and "leader/follower" for the same single-leader idea; most current documentation prefers the last two.
Checklist
- What happens to writes if the leader or a region is lost, and how long?
- How much data can we lose (RPO) and how long can we be down (RTO)?
- How do we handle stale reads from replicas?
- Who resolves conflicts, and how?
- Have we practised failover?
Real-world reading
Related reading
- Active-Active for Multi-Regional ResiliencyNetflix Engineering · NetflixCase Studies
- Designing Data-Intensive ApplicationsMartin Kleppmann · O'ReillyBooks
- Read Consistency with Database Replicas at ShopifyShopify engineers · ShopifyCase Studies
- Uber Schemaless: A Scalable MySQL DatastoreUber Engineering · UberCase Studies
Show 6 moreShow fewer
- Mitigating MySQL Replication Lag and Reducing Read Load at GithubGithub engineers · GithubCase Studies
- Cassandra architecture overviewApache Cassandra · Apache Software FoundationDocumentation
- How Discord Stores Trillions of MessagesBo Ingram · DiscordBlogs
- Spanner: Google's Globally Distributed Database (paper)Corbett et al. · GooglePapers
- Scaling Multitenant Architecture Across Multiple Data Centres at Shopify - Weingarten, Engineering Lead at ShopifyShopifyYouTube
- MIT 6.824: Distributed SystemsRobert Morris · MITCourses
System Design Foundations · 11 minReplication and shardingTwo ways to spread data over many machines: copy it for safety and read speed, or split it for capacity.Read here
Replication: keep copies
Replication keeps the same data on more than one machine. Reasons:
- Availability: if one machine dies, another has the data.
- Read capacity: reads can go to any copy.
- Locality: place a copy near users in another region.
The most common arrangement is leader and followers. All writes go to the leader, which sends the changes to followers. Reads can use followers.
100%Figure SDA-FND-05-1 · Leader and follower replication · © forcsguy.com
Many teams hide the split between the primary and the replicas behind a small router, so the application does not need to know:
100%Figure SDA-FND-05-2 · Read and write splitting through a router · © forcsguy.com
Synchronous or asynchronous
- Synchronous: the leader waits for followers to confirm before saying "done". Safer, but slower, and a down follower can block writes.
- Asynchronous: the leader confirms immediately and followers catch up. Fast, but a follower can be behind, and a leader crash can lose the most recent writes.
Most systems use asynchronous replication for most followers, sometimes with one synchronous follower as a safety net.
Replication lag
Because followers can lag, a user may write something and then read an older value from a follower. Fixes include reading the user's own recent writes from the leader, or tracking how fresh each replica is. This is the first taste of a bigger idea, consistency, covered in lesson 7.
When the leader fails
A follower must be promoted (failover). That needs failure detection and agreement on who the new leader is, so that two machines do not both believe they are the leader (a split brain). This is why teams rely on tested tooling or managed databases for failover rather than hand-written scripts.
Read-after-write consistency
With asynchronous replicas, a user can save something and then not see it: the write went to the primary, the next read hit a replica that is a few seconds behind. Three common fixes:
- Send reads that must be fresh (the user's own profile, an order just placed) to the primary.
- For a short window after a user writes, route that user's reads to the primary.
- Let the router check whether a replica has caught up to the user's last write; if not, read from the primary or wait.
A database proxy in front of the cluster can do this routing so application code stays simple, at the cost of one more hop and one more component that must itself be highly available.
Before: one database
100%After: primary with read replicas
100%What changed
- Reads are spread across copies
- A copy can be promoted if the primary fails
- Replicas may lag slightly behind the primary
Sharding: split the data
Replication does not help when the data or the writes no longer fit on one machine. Sharding (partitioning) divides the data so each shard holds a part. Each shard is usually replicated too.
100%Figure SDA-FND-05-3 · Sharding by key range · © forcsguy.com
Choosing a shard key
The shard key decides which shard owns a row. A good key:
- Spreads data evenly, so no shard is much bigger than the others.
- Spreads traffic evenly, so no shard is a hot spot.
- Matches your queries, so most queries touch one shard.
Common schemes:
Scheme How Watch out for Range key ranges per shard hot spots, e.g. newest dates Hash hash(key) mod N adding shards remaps most keys Directory a lookup table says where each key lives the directory is another thing to run and scale Consistent hashing keys and nodes placed on a ring needs virtual nodes to balance well Consistent hashing in one picture
Place both servers and keys on a ring. A key belongs to the first server clockwise from it. Adding a server only takes keys from its neighbour; the rest do not move.
100%Figure SDA-FND-05-4 · Consistent hashing ring · © forcsguy.com
Horizontal and vertical partitioning
Sharding is horizontal partitioning: the rows of a table are split across machines, each shard holding the same columns for a different set of rows. Vertical partitioning splits by columns or by feature instead: rarely used or large columns (a profile photo, a long description) move to a separate table or store, or whole groups of tables go to different databases (users on one, orders on another). It is simpler than sharding and keeps frequently read data small and fast, but it does not help when a single table's rows outgrow one machine.
100%Figure SDA-FND-05-5 · Splitting a table by rows and by columns · © forcsguy.com
What sharding costs you
- Cross-shard queries and joins become slow or need extra work.
- Transactions across shards are hard (lesson 8 touches on how systems cope).
- Rebalancing when a shard gets too big is operational work.
- More moving parts to monitor.
A worked example: sizing replicas and shards
Replicas for reads. A social app has 20,000 reads and 1,000 writes per second. One database node can do about 5,000 simple operations per second. A primary alone is hopeless. With writes of 1,000 per second on the primary, you have capacity left for about 4,000 reads, so you need at least four replicas to serve 20,000 reads (16,000 on replicas plus 4,000 on the primary) with no headroom, so six in practice. Adding replicas scales reads almost linearly. It does nothing for the 1,000 writes, which still all go to one primary.
Shards for writes. If writes grow to 12,000 per second, no single primary can take them. Split the data into shards, each with its own primary: with 4 shards each takes about 3,000 writes per second. Each shard then has its own replicas for reads. Your final count is shards x (1 primary + replicas), for example 4 x (1 + 2) = 12 database nodes.
100%Figure SDA-FND-05-6 · Replicas scale reads, shards scale writes · © forcsguy.com
Walking through a failover
Replication is only useful if you know what happens when a primary dies. With asynchronous replication:
- The primary acknowledges writes 100 to 140, but the follower has only received up to 135 (replication lag).
- The primary crashes. Writes 136 to 140 exist only on the dead machine.
- A monitor notices missing heartbeats, usually after several seconds, and promotes the most up-to-date follower to primary.
- Clients are redirected. Writes 136 to 140 are lost (or recoverable only when the old primary returns).
- When the old primary comes back it must not accept writes as if nothing happened (that would create two primaries, "split brain"); it rejoins as a follower and discards or reconciles what the new primary does not have.
With synchronous replication to at least one follower, step 2 loses nothing, but every write waits for that follower, adding latency and making writes fail if the follower is unavailable. Many systems choose a compromise: wait for one follower to confirm (semi-synchronous), accepting a little latency to avoid losing acknowledged writes.
100%Figure SDA-FND-05-7 · What an asynchronous failover can lose · © forcsguy.com
Choosing a shard key: three examples
- User id for a messaging app. Almost every query is "this user's messages", so a hash of the user id keeps each user's data together and spreads users evenly. The pain: a query across all users (an admin search) must ask every shard.
- Order date for an orders table. Range sharding by date makes "last month's orders" cheap, but all new writes land on the newest shard, a hot spot, while old shards sit idle. A better key adds a hash of the customer id.
- Country for a multi-region product. Good for keeping data near users and meeting data-residency rules, but shards are uneven: one country may hold half your users.
A good key has high cardinality (many distinct values), even load and matches your most common query. Changing it later means moving most of your data, so test it against a sample of real traffic first.
Mistakes people make
- Reading from a replica right after writing. The replica may not have the write yet, so users do not see their own change. Read your own writes from the primary for a short time, or route that user to the primary.
- Sharding too early. Sharding multiplies operational work: backups, schema changes, cross-shard queries and transactions all get harder. First try indexes, caching, replicas and a bigger machine.
- Counting on replicas as backups. A mistaken delete is replicated within milliseconds. Keep real backups and test restoring them.
- Forgetting to rebalance. Shards grow unevenly. Plan how to split a shard, ideally with consistent hashing or many small virtual shards that you can move between machines.
Try it yourself
In the System Builder, open "The database goes down". Run it with no replicas and see reads and writes fail, then add replicas and a write queue and compare. For hashing itself, build the consistent hash ring lab and measure how many keys move when you add a node. To place replicas and a queue yourself, open the database-outage design on the free canvas and kill the database.
More on this site
Related reading
- How Discord Stores Trillions of MessagesBo Ingram · DiscordBlogs
- MongoDB: Shard KeysMongoDB · MongoDB Inc.Documentation
- Uber Schemaless: A Scalable MySQL DatastoreUber Engineering · UberCase Studies
- How Discord Stores Billions of MessagesDiscordCase Studies
Show 6 moreShow fewer
- Consistent Hashing and Random Trees (paper)Karger et al. · MITPapers
- Amazon Dynamo: Highly Available Key-Value StoreWerner Vogels · AmazonCase Studies
- Mitigating MySQL Replication Lag and Reducing Read Load at GithubGithub engineers · GithubCase Studies
- MongoDB at Baidu: Multi-Tenant Cluster Storing 200+ Billion Documents across 160 ShardsMongodb engineers · MongodbCase Studies
- Shopify EngineeringShopify engineers · ShopifyBlogs
- Sharding MySQL at QuoraQuora engineers · QuoraCase Studies
Core Concepts: How Things Actually Work · 7 minDurability: replication and erasure codingHow storage systems survive disk failures without storing three full copies of everything.Read here
Why durability is hard
Disks fail every day in a large fleet. Durability is the probability data is not lost over time, and cloud object storage advertises numbers like eleven nines. How?
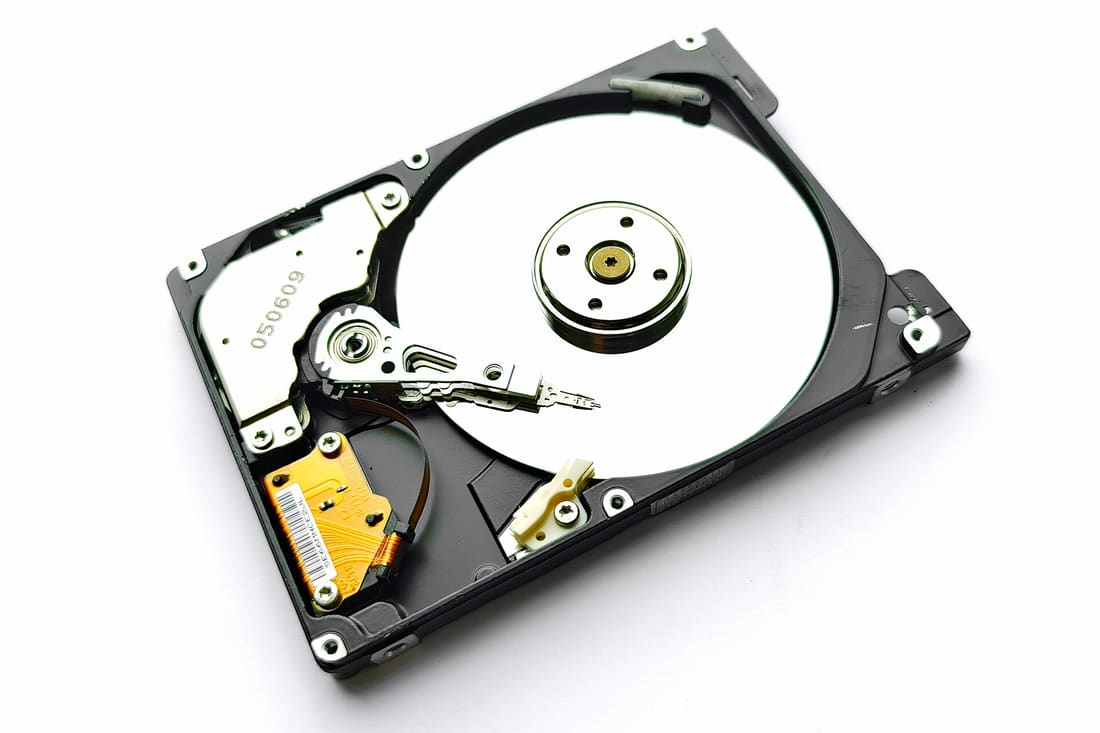 Image: Mk2010 · CC BY 4.0 · Source · Wikimedia Commons: Hard disk drive platter, Samsung MP0402H
Technique 1: replication
Keep N full copies on different machines, racks and zones. Simple and fast:
- Any copy can serve a read.
- Recovery is just copying a replica.
- Cost: 3 copies mean 3x storage.
Technique 2: erasure coding
Split an object into k data pieces, compute m parity pieces (using maths such as Reed-Solomon), and store all k + m pieces on different machines. Any k of the k + m pieces can rebuild the original.
100%Figure SDA-CORE-14-1 · Technique 2: erasure coding · © forcsguy.com
With (6, 3) you store 9 pieces for 6 pieces of data: 1.5x overhead, and you can lose any 3 disks. That beats 3x replication on both counts.
100%Figure SDA-CORE-14-2 · Surviving two failures and rebuilding · © forcsguy.com
The trade-offs
Replication Erasure coding Storage overhead high (3x) low (about 1.2x to 1.5x) Read from one copy, fast read several pieces, fast if all data pieces present Repair copy one replica read many pieces and recompute Small updates easy costly (re-encode) Best for hot, small, frequently changed data cold, large, rarely changed objects Making it real
- Placement: put pieces in different failure domains (disk, server, rack, zone) so one event cannot take many.
- Detection and repair: monitor continuously, and rebuild lost pieces before more fail. The faster the repair, the higher the durability.
- Checksums: verify data on read and in background scrubbing to catch silent corruption.
- Tiering: hot data replicated; older data converted to erasure coding.
- Versioning and backups protect against human error, which replication does not (a delete replicates too).
More on this site
Related reading
- Uber Schemaless: A Scalable MySQL DatastoreUber Engineering · UberCase Studies
- How Discord Stores Trillions of MessagesBo Ingram · DiscordBlogs
- Jordan Has No Life: Systems Design Concepts SeriesJordan · Jordan Has No LifeYouTube
- Inside the Magic PocketDropboxCase Studies
Show 6 moreShow fewer
- Kafka Source & DocsApache Software Foundation · apacheGitHub
- Black-Box Auditing: Verifying End-to-End Replication Integrity between MySQL and Redshift at YelpYelp engineers · YelpCase Studies
- Apache CassandraApache Software Foundation · GitHubGitHub
- Types of Replication - SQL ServerMicrosoft engineers · MicrosoftCase Studies
- Concept && CodingShrayansh Jain · Concept && CodingYouTube
- Accelerator: Fast Data Processing Framework at eBayeBay engineers · eBayCase Studies
Go deeper on this
A path through videos, articles, other case studies and code on the same ideas as MIT 6.824: Distributed Systems.
Warm upGet the vocabulary first.
Books · Free from the author
Concurrent and Distributed Systems (Cambridge lecture notes)
Eight lectures on time, broadcast, replication, consensus and transactions, with notes, slides and video. Free from the author under CC BY-SA.
University of CambridgeIntermediate
Books · Free from the author
Distributed Systems for Fun and Profit
A short, readable tour of time, consistency and replication in distributed systems, free to read online from the author.
mixu.netBeginner
WatchHow others solve the same problem, on video.
Videos belong to their creators and play from YouTube. More on YouTube (opens in a new tab)
ReadEngineers explain it in their own words.
Papers
In Search of an Understandable Consensus Algorithm (Raft paper)
The Raft paper: leader election, log replication and safety explained so that engineers can implement them.
Stanford UniversityAdvanced
Blogs
Jepsen analyses
Tests of real databases under failure, showing which consistency promises hold.
JepsenAdvanced
See it in another companyThe same ideas, a different system.
Case Studies · Read here
Amazon Dynamo: Highly Available Key-Value Store
Werner Vogels' write-up of the design that inspired DynamoDB, Cassandra and Riak.
AmazonAdvanced
Case Studies · Read here
Read Consistency with Database Replicas at Shopify
At Shopify, we’ve long used database replication for redundancy and failure recovery, but only fairly recently started to explore the potential of replicas as an alternative read-only data source for applications.
ShopifyIntermediate
Read the codeSee how it looks when it is real.
GitHub
Kafka Source & Docs
Apache Kafka source code: read the log, replication and consumer-group internals first-hand.
apacheAdvanced
GitHub
CockroachDB
A distributed SQL database built on ranges, Raft and MVCC.
GitHubAdvanced
Keep learning
Loading community…