Library / Case Studies
Inside the Magic Pocket
How Dropbox built its own exabyte-scale block storage, including durability and cost choices.
By Dropbox · Dropbox · Added 2026-10-12
All content belongs to Dropbox. We only link to it and give credit. Report a problem
Learn this case study
About 37 min left. Your work is saved as you go.
What you are about to study
Dropbox explains a real system. It assumes you are comfortable with distributed systems.
Ideas you will meet
- Storage Engines
- Write-ahead logs, B-trees and LSM-trees.
- Replication
- Leader/follower, multi-leader and leaderless replication.
What we already know about this
Our own lessons on these ideas. Read them here before you start, so it makes sense.
Core Concepts: How Things Actually Work · 7 minDurability: replication and erasure codingHow storage systems survive disk failures without storing three full copies of everything.Read here
Why durability is hard
Disks fail every day in a large fleet. Durability is the probability data is not lost over time, and cloud object storage advertises numbers like eleven nines. How?
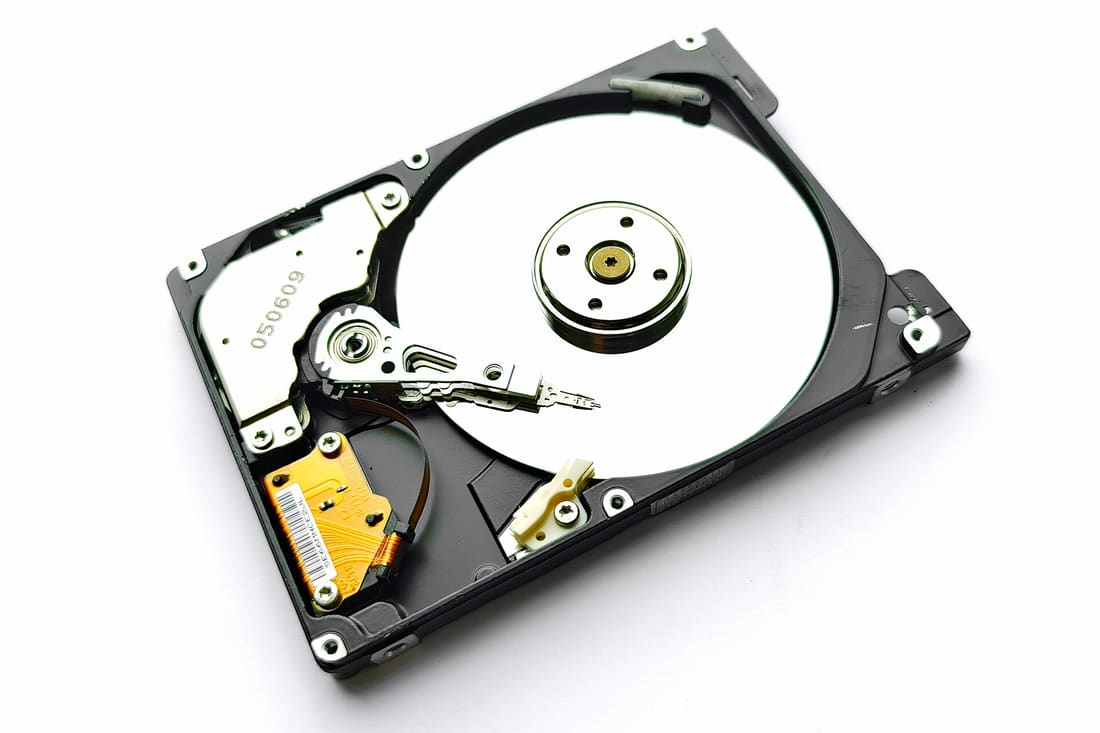 Image: Mk2010 · CC BY 4.0 · Source · Wikimedia Commons: Hard disk drive platter, Samsung MP0402H
Technique 1: replication
Keep N full copies on different machines, racks and zones. Simple and fast:
- Any copy can serve a read.
- Recovery is just copying a replica.
- Cost: 3 copies mean 3x storage.
Technique 2: erasure coding
Split an object into k data pieces, compute m parity pieces (using maths such as Reed-Solomon), and store all k + m pieces on different machines. Any k of the k + m pieces can rebuild the original.
100%Figure SDA-CORE-14-1 · Technique 2: erasure coding · © forcsguy.com
With (6, 3) you store 9 pieces for 6 pieces of data: 1.5x overhead, and you can lose any 3 disks. That beats 3x replication on both counts.
100%Figure SDA-CORE-14-2 · Surviving two failures and rebuilding · © forcsguy.com
The trade-offs
Replication Erasure coding Storage overhead high (3x) low (about 1.2x to 1.5x) Read from one copy, fast read several pieces, fast if all data pieces present Repair copy one replica read many pieces and recompute Small updates easy costly (re-encode) Best for hot, small, frequently changed data cold, large, rarely changed objects Making it real
- Placement: put pieces in different failure domains (disk, server, rack, zone) so one event cannot take many.
- Detection and repair: monitor continuously, and rebuild lost pieces before more fail. The faster the repair, the higher the durability.
- Checksums: verify data on read and in background scrubbing to catch silent corruption.
- Tiering: hot data replicated; older data converted to erasure coding.
- Versioning and backups protect against human error, which replication does not (a delete replicates too).
More on this site
Related reading
- Uber Schemaless: A Scalable MySQL DatastoreUber Engineering · UberCase Studies
- How Discord Stores Trillions of MessagesBo Ingram · DiscordBlogs
- Jordan Has No Life: Systems Design Concepts SeriesJordan · Jordan Has No LifeYouTube
- Inside the Magic PocketDropboxCase Studies
Show 6 moreShow fewer
- Kafka Source & DocsApache Software Foundation · apacheGitHub
- Black-Box Auditing: Verifying End-to-End Replication Integrity between MySQL and Redshift at YelpYelp engineers · YelpCase Studies
- Apache CassandraApache Software Foundation · GitHubGitHub
- Types of Replication - SQL ServerMicrosoft engineers · MicrosoftCase Studies
- Concept && CodingShrayansh Jain · Concept && CodingYouTube
- Accelerator: Fast Data Processing Framework at eBayeBay engineers · eBayCase Studies
Classic System Designs · 14 minDesign a key-value storeA Dynamo-style distributed store: partitioning, replication, quorums, conflict handling and how reads and writes reach disk.Read here
The problem
A key-value store supports
put(key, value)andget(key). A distributed one must also:- Store far more than one machine can hold.
- Keep serving when machines or networks fail.
- Have low latency for both reads and writes.
- Let you tune consistency against availability.
We use a Dynamo-style design, which is the model behind several widely used stores.
Partition the data
Spread keys across nodes with consistent hashing (previous lesson). Virtual nodes keep the load even and let you add capacity gradually. Any node can act as the coordinator for a request, so there is no single leader to bottleneck on.
Replicate each key
Copy every key to N nodes: the owner and the next N-1 distinct nodes clockwise on the ring. Spread replicas across racks or zones so one failure does not take out all copies.
100%Figure SDA-CSD-03-1 · Replicating each key to N nodes · © forcsguy.com
Tunable consistency with quorums
Choose three numbers:
- N: number of replicas.
- W: replicas that must acknowledge a write.
- R: replicas that must answer a read.
Setting Behaviour W + R > NReads overlap the latest write: strong-ish consistency W = 1, R = 1Fastest and most available, but reads can be stale W = N, R = 1Fast reads, writes fail if any replica is down You pick the trade-off per use case, which is what makes this design flexible.
A quorum write, step by step
100%Figure SDA-CSD-03-2 · Coordinator and a write quorum (N=3, W=2) · © forcsguy.com
When replicas disagree
Replicas can hold different versions, for example after a partition.
- Versioning: attach a version (a vector clock) to each value so the system can tell whether one version supersedes another or they were concurrent.
- Reconciliation: for concurrent versions, either the application merges them (shopping cart: union the items) or the system uses a simple rule such as last-write-wins, which can silently discard data.
Two writers at once: conflicts and vector clocks
100%Figure SDA-CSD-03-3 · Concurrent writes create two versions · © forcsguy.com
100%Figure SDA-CSD-03-4 · Vector clocks across writes · © forcsguy.com
A clock A is an ancestor of B if every counter in A is less than or equal to the matching counter in B. If each has some counter larger than the other's, the versions are siblings and need merging.
Failure handling
- Detection: nodes exchange gossip messages about who is alive, so there is no central monitor to fail.
- Temporary failure: if a replica is down, another node accepts the write and stores a hint, handing it over when the replica returns (hinted handoff).
- Permanent repair: periodically compare replicas using Merkle trees (hashes of key ranges) and copy only what differs (anti-entropy).
- Data centre failure: replicate across regions for the keys that need it.
Noticing failures: gossip
100%Figure SDA-CSD-03-5 · Gossip failure detection · © forcsguy.com
Staying available through a short outage
100%Figure SDA-CSD-03-6 · Sloppy quorum and hinted handoff · © forcsguy.com
Repairing replicas for good: Merkle trees
100%Figure SDA-CSD-03-7 · Comparing replicas with Merkle trees · © forcsguy.com
More failure-handling detail
- Do not trust one witness. One node saying "that server is down" is not enough; require agreement from several independent sources (gossip gives this naturally: a node is marked down only after others also see its heartbeat counter stall).
- Sloppy quorum. A strict quorum can block when the usual replicas are down. Instead, take the first healthy servers on the ring for the write or read, and let a stand-in hold the data with a "hint". When the real replica returns, the stand-in hands the data back (hinted handoff). You gain availability and give up the strict overlap guarantee for a while.
- Replica placement. When walking the ring for N replicas, skip virtual nodes that belong to a server already chosen, and spread replicas across data centers, because nodes in one site often fail together.
- Bigger machines. Give a more powerful server more virtual nodes so it takes a proportionally larger share.
- Conflicting versions. Vector clocks grow as more servers touch a key; cap their length and accept that, rarely, old entries dropped make some conflicts harder to untangle.
Inside one node: how writes and reads hit disk
100%Figure SDA-CSD-03-8 · Write and read path on one node · © forcsguy.com
Write path
- Append to a commit log (sequential, fast, crash-safe).
- Apply to an in-memory sorted structure (the memtable).
- When the memtable is full, flush it to an immutable sorted file on disk; background compaction merges files.
Read path
- Check the memtable.
- If missing, check the files, using a Bloom filter per file to skip files that definitely do not contain the key.
- Merge results, newest wins.
This log-structured design turns random writes into sequential ones, which is why such stores handle huge write volumes.
One node, many jobs
100%Figure SDA-CSD-03-9 · What every node does · © forcsguy.com
Summary of the design
Concern Technique Scale out Consistent hashing with virtual nodes Durability and availability N replicas across zones Consistency dial Quorums (W, R) Conflicts Vector clocks and merge logic Failure detection Gossip Temporary and permanent repair Hinted handoff, Merkle-tree anti-entropy Fast writes Commit log, memtable, sorted files Worked numbers: how many nodes?
Target: 1 billion keys averaging 1 KB, with 3 replicas, serving 100,000 operations per second.
- Raw data: 1 B x 1 KB = 1 TB. With three replicas, 3 TB of storage across the cluster, before overhead for indexes and compaction (plan for about 2x headroom on disk for compaction, so around 6 TB).
- Per-node capacity: if one node comfortably holds 1 TB of data and serves about 10,000 operations per second, 12 to 15 nodes cover both storage (3 TB / 1 TB, with room) and throughput (100,000 / 10,000 x 3 for replication on writes and headroom).
- With a 20-node ring each node owns about 5% of the keys, and losing one node moves its 5% (about 150 GB of replicas) to its neighbours: repair takes minutes to hours, which is why you keep spare capacity.
When a replica is down: hinted handoff
With W = 2 of N = 3, a write must reach two replicas. Suppose node C is down.
- The coordinator sends the write to A, B and C; A and B acknowledge, so the write succeeds.
- For C, a hint ("this write was meant for C") is stored on a healthy node.
- When C returns, the holder of the hint replays the write to C.
If the node is down for too long the hints are dropped, and a slower anti-entropy repair takes over.
100%Figure SDA-CSD-03-10 · A write while one replica is down · © forcsguy.com
Anti-entropy with Merkle trees
Replicas can still drift apart (a hint was lost, a disk was corrupted). Comparing every key between two replicas is far too expensive. A Merkle tree summarises a key range with hashes: each leaf is a hash of a small bucket of keys, and each parent is a hash of its children. Two replicas compare root hashes; if equal, the whole range matches. If not, they compare the children and descend only into the branches that differ, until they find the few buckets that actually disagree and exchange just those keys.
100%Figure SDA-CSD-03-11 · Finding differences without comparing every key · © forcsguy.com
Mistakes people make
- Hot keys. One extremely popular key overloads its replicas whatever the cluster size. Cache it in front or split it into several keys.
- Large values. Multi-megabyte values hurt latency and replication; store big blobs in object storage and keep a pointer.
- Expecting joins and secondary queries. A key-value store answers "get by key". If you need other queries, add an index structure or use another database.
- Resolving conflicts with wall-clock time alone. Skewed clocks lose writes; prefer version vectors or let the application merge.
- Forgetting tombstones. Deletes leave markers that must live long enough to reach all replicas, and be compacted away later. Skipping this resurrects deleted data.
- Never running repair. Without regular anti-entropy, rarely read data can silently diverge.
Try it yourself
Build the consistent hash ring lab to see how few keys move when a node joins, the Bitcask lab for one node's storage engine, and the write-ahead log lab for crash recovery. Then read the consistency and CAP lesson for the quorum rule used above.
More on this site
Related reading
- Amazon Dynamo: Highly Available Key-Value StoreWerner Vogels · AmazonCase Studies
- The Google File System (paper)Ghemawat, Gobioff and Leung · GooglePapers
- The Log-Structured Merge-Tree (paper)O'Neil et al. · UMass BostonPapers
- Time, Clocks, and the Ordering of Events in a Distributed System (paper)Leslie Lamport · Microsoft ResearchPapers
Show 6 moreShow fewer
- ZippyDB: Facebook's key-value storeMeta Engineering · MetaCase Studies
- Inside the Magic PocketDropboxCase Studies
- Spanner: Google's Globally Distributed Database (paper)Corbett et al. · GooglePapers
- Read Consistency with Database Replicas at ShopifyShopify engineers · ShopifyCase Studies
- Designing Large-Scale SystemsSomethingsimilar engineers · SomethingsimilarBlogs
- Reddit Inc Blog HomepageRedditblog engineers · RedditblogBlogs
Databases Deep Dive · 12 minReplication topologies and multi-region databasesSingle-leader, multi-leader and leaderless replication, how they handle conflicts and lag, and what changes across regions.Read here
Why replicate
Replication keeps copies of data on several machines for three reasons: availability (survive a node failure), read scaling (serve reads from replicas) and latency (put data near users). The hard part is keeping copies consistent while writes continue. (Basics are in the replication and sharding lesson of the foundations course; this lesson compares the topologies.)
Single-leader (primary and replicas)
One node, the leader (primary or master), accepts writes and ships its changes to followers (replicas), which serve reads.
100%Figure SDA-DDV-04-1 · Single-leader replication · © forcsguy.com
- Synchronous replication waits for a follower before acknowledging: safer, slower, and a stalled follower can block writes. Asynchronous is faster but a failover can lose the latest writes. A common compromise: one synchronous follower, others asynchronous.
- Failover must detect failure, choose the most up-to-date replica, redirect clients and ensure the old leader does not come back believing it still leads (split brain).
- Replication lag causes stale reads. Techniques: read-your-writes (route a user's reads to the leader shortly after they write), monotonic reads (keep a user on one replica), and checking replica position.
Multi-leader
Several nodes accept writes (often one per region) and replicate to each other. Benefits: local write latency and continued operation if a region is cut off. Cost: write conflicts.
Conflict handling options:
- Avoid them: route all writes for one record to one leader (for example by user or region).
- Last write wins by timestamp: simple, but silently drops one of two concurrent updates and depends on clocks.
- Merge values (union of sets, counters) using mergeable data types (CRDTs; see the collaborative editing lesson).
- Custom resolution in application code, or ask the user.
Multi-leader also appears in offline-capable apps (each device is a leader) and collaborative editing.
Before: single leader
100%After: multi-leader across regions
100%What changed
- Users in each region write to a nearby database
- Concurrent edits to the same row need conflict handling
- More moving parts to run and monitor
Leaderless (Dynamo-style)
Any replica accepts writes; clients write to several replicas and read from several, using quorums (
W + R > N) to get fresh data (see the key-value store lesson). Background anti-entropy and read repair fix stale copies; versions or vector clocks detect conflicts. It favours availability and is typical of Cassandra and DynamoDB-style stores.100%Figure SDA-DDV-04-2 · Choosing a replication model · © forcsguy.com
Multi-region designs
- Active-passive: one region serves writes; another is a warm standby. Simple; failover loses a little data (the replication lag) and takes minutes.
- Active-active: several regions serve traffic. Requires either partitioning data by home region (each record has one home, cross-region reads are replicas) or true multi-leader conflict handling.
- Global databases use consensus across regions (see the consensus lesson) for strong consistency at the cost of cross-region write latency; some offer tunable consistency per query.
- Latency numbers matter: a cross-ocean round trip is around 100 ms or more, so synchronous cross-region replication adds that to every write.
- Data residency laws may require keeping certain users' data in a region.
Partitioning and replication together
Real systems shard data into partitions and replicate each partition (a leader per partition spreads write load across nodes). Rebalancing, hot partitions and cross-partition transactions are the new problems (see sharding and the consistent-hashing lesson).
Master/slave naming
You will see "master/slave", "primary/replica" and "leader/follower" for the same single-leader idea; most current documentation prefers the last two.
Checklist
- What happens to writes if the leader or a region is lost, and how long?
- How much data can we lose (RPO) and how long can we be down (RTO)?
- How do we handle stale reads from replicas?
- Who resolves conflicts, and how?
- Have we practised failover?
Real-world reading
Related reading
- Active-Active for Multi-Regional ResiliencyNetflix Engineering · NetflixCase Studies
- Designing Data-Intensive ApplicationsMartin Kleppmann · O'ReillyBooks
- Read Consistency with Database Replicas at ShopifyShopify engineers · ShopifyCase Studies
- Uber Schemaless: A Scalable MySQL DatastoreUber Engineering · UberCase Studies
Show 6 moreShow fewer
- Mitigating MySQL Replication Lag and Reducing Read Load at GithubGithub engineers · GithubCase Studies
- Cassandra architecture overviewApache Cassandra · Apache Software FoundationDocumentation
- How Discord Stores Trillions of MessagesBo Ingram · DiscordBlogs
- Spanner: Google's Globally Distributed Database (paper)Corbett et al. · GooglePapers
- Scaling Multitenant Architecture Across Multiple Data Centres at Shopify - Weingarten, Engineering Lead at ShopifyShopifyYouTube
- MIT 6.824: Distributed SystemsRobert Morris · MITCourses
Go deeper on this
A path through videos, articles, other case studies and code on the same ideas as Inside the Magic Pocket.
Warm upGet the vocabulary first.
Books · Free from the author
Readings in Database Systems (the Red Book)
Essays and papers on how database systems are built, with an introduction to each, free online from the editors.
Red BookAdvanced
Books
Database Internals
How storage engines and distributed databases work, from B-trees and LSM-trees to consensus and replication.
O'ReillyAdvanced
WatchHow others solve the same problem, on video.
Videos belong to their creators and play from YouTube. More on YouTube (opens in a new tab)
ReadEngineers explain it in their own words.
Papers · Read here
Amazon Aurora: Design Considerations for High Throughput Cloud-Native Relational Databases (paper)
Why Aurora moves the redo log to a distributed storage layer, so replication and crash recovery become cheap.
Amazon Web ServicesAdvanced
Papers
The Google File System (paper)
How Google built a file system for huge files and constant machine failures: one master for metadata, many chunk servers, and append-heavy workloads. The ancestor of HDFS.
GoogleAdvanced
See it in another companyThe same ideas, a different system.
Case Studies · Read here
ZippyDB: Facebook's key-value store
Facebook's strongly consistent key-value store built on RocksDB and Paxos, with data sharded and replicated.
MetaAdvanced
Case Studies · Read here
Amazon Dynamo: Highly Available Key-Value Store
Werner Vogels' write-up of the design that inspired DynamoDB, Cassandra and Riak.
AmazonAdvanced
Read the codeSee how it looks when it is real.
GitHub
Kafka Source & Docs
Apache Kafka source code: read the log, replication and consumer-group internals first-hand.
apacheAdvanced
GitHub
CockroachDB
A distributed SQL database built on ranges, Raft and MVCC.
GitHubAdvanced
Keep learning
Loading community…