Library / Blogs
Amazon Builders' Library
How Amazon builds reliable systems: timeouts, retries, backoff, load shedding.
By Amazon Engineers · Amazon Web Services · Added 2026-09-09
All content belongs to Amazon Engineers / Amazon Web Services. We only link to it and give credit. Report a problem
Learn this article
About 37 min left. Your work is saved as you go.
What you are about to study
Amazon Web Services wrote this to explain how they thought about a problem. It assumes you are comfortable with distributed systems.
Ideas you will meet
- Distributed Systems
- Consensus, time, failure and the fundamentals of scale-out.
- Rate Limiting
- Token bucket, leaky bucket and sliding-window limiters.
- Microservices
- Decompose systems into independently deployable services.
What we already know about this
Our own lessons on these ideas. Read them here before you start, so it makes sense.
Real-World Systems · 11 minHow microservices work togetherSynchronous calls, events, sagas and discovery: how separate services cooperate without becoming one tangled system.Read here
What a microservice architecture is
Instead of one large application, the system is split into small services, each responsible for one business capability (orders, payments, inventory, users). Services are deployed and scaled independently, often by different teams, and talk over the network.
The benefits are independent deployment, team autonomy and targeted scaling. The cost is that everything that used to be a function call is now a network call that can be slow or fail, and data is spread across services.
Ways services talk
Style How Good for Cost Synchronous request and response (REST, gRPC) Caller waits for the answer Queries and steps the user waits for Coupling in time; failures propagate Asynchronous messages and events (queues, streams) Caller publishes and moves on Reactions, workflows, decoupling Eventual consistency; harder to trace 100%Figure SDA-RWS-13-1 · Services: sync calls, events and owned data · © forcsguy.com
100%Figure SDA-RWS-13-2 · Two ways to run a multi-step process · © forcsguy.com
Before: a chain of synchronous calls
100%After: events between services
100%What changed
- A slow service no longer blocks the order
- New services can listen without changing the sender
- The result is eventually consistent, so design for that
Data ownership
Each service owns its own data and exposes it only through its API or events. No other service reads its tables. This keeps boundaries real, but it means you cannot join across services in SQL: you call APIs or keep read models built from events.
Keeping things consistent: sagas
A business action often spans services (take payment, reserve stock, create shipment). A single database transaction cannot cover them. A saga is a sequence of local transactions, each with a compensating action:
- Create the order (pending).
- Reserve stock. Compensation: release stock.
- Charge the payment. Compensation: refund.
- Confirm the order. If any step fails, run the compensations for earlier steps in reverse.
Two ways to run a saga:
- Choreography: services react to each other's events. Simple and decoupled, but the overall flow is spread out and hard to see.
- Orchestration: a coordinator (an orchestrator service or workflow engine) tells each service what to do next and handles failures. The flow is explicit and easier to reason about.
The outbox pattern
A service must update its database and publish an event, and one may succeed without the other. Write the event to an outbox table in the same transaction, and let a separate process publish it. Consumers must be idempotent, because delivery is at least once.
Finding and reaching services
- Service discovery (via the platform, DNS or a registry) tells callers where healthy instances are, since addresses change constantly.
- An API gateway is the front door for external clients: routing, authentication, rate limiting. A backend for frontend shapes responses for a specific client.
- A service mesh adds a sidecar proxy next to each service to provide mutual TLS, retries, timeouts and metrics without changing application code.
Resilience between services
Reuse the reliability tools: timeouts, retries with backoff and jitter, circuit breakers and bulkheads. Prefer asynchronous communication where a user does not need an immediate answer.
Operating many services
- Distributed tracing with a correlation id shows a request's path across services.
- Contract testing and careful API versioning let teams change without breaking each other.
- Beware the distributed monolith: services so entangled they must be deployed together, which gives you all the costs and none of the benefits. Split along business boundaries, not technical layers.
- Start with a well-structured monolith if the team is small. Split when a real need appears.
More on this site
Related reading
- Pattern: Transactional outboxChris Richardson · microservices.ioDocumentation
- Pattern: SagaChris Richardson · microservices.ioDocumentation
- Awesome MicroservicesMehdi Fornos · mfornosGitHub
- Microservices PatternsChris Richardson · ManningBooks
Show 6 moreShow fewer
- Tech Dummies: System Design Case StudiesNarendra L · Tech DummiesYouTube
- Payment Transaction Management in Microservices at MercariMercari engineers · MercariCase Studies
- Circuit BreakerMartin FowlerBlogs
- Avoiding insurmountable queue backlogsAmazon Builders' Library · Amazon Web ServicesBlogs
- Microservice Architecture at MediumMedium engineers · MediumCase Studies
- Back-end at FlickrFlickr engineers · FlickrCase Studies
Messaging and Microservice Patterns · 13 minOperating microservices: config, secrets, feature flags, tracing and loggingThe operational toolkit around a service: configuration and secrets done safely, feature flags for controlled releases, and traces and logs that follow a request across services.Read here
Configuration
Separate configuration from code. Anything that changes between environments (database address, feature limits, endpoints) should come from environment variables, config files or a config service, not be baked into the build ("build once, run anywhere").
- Keep defaults in code and overrides in the environment.
- Validate configuration at start-up and fail fast with a clear message.
- For values that must change at runtime, use a config service or watch a mounted file, and treat changes like deployments (versioned, reviewed, auditable).
- Keep config in version control (as code or templates) so changes are reviewed and reversible.
Secrets
Secrets (passwords, API keys, private keys, tokens) need stricter handling.
- Never commit them, put them in images, or print them in logs.
- Store them in a secrets manager (a cloud service, HashiCorp Vault, or an encrypted platform secret store) with access control, audit logs and encryption at rest.
- Inject at runtime (environment, mounted file or an agent), and use short-lived credentials where possible (cloud roles, dynamic database credentials).
- Rotate regularly and after any suspected leak; design services to reload secrets without downtime.
- Least privilege: each service gets only its own secrets.
Feature flags
A feature flag is a runtime switch controlling whether code runs, separate from deployment.
100%Figure SDA-MSV-05-1 · Deploy is not release · © forcsguy.com
Uses: gradual rollout, kill switches for risky features, A/B tests, per-customer entitlements, and decoupling release from deploy (see the deployment strategies lesson). Cautions: flags multiply test combinations, can be left in place forever, and a flag service outage must fail to a safe default.
Distributed tracing
A request through a microservice system touches many services. A trace records the whole journey as a tree of spans (one per operation), joined by a trace id passed in request headers.
100%Figure SDA-MSV-05-2 · One request traced across services · © forcsguy.com
- OpenTelemetry is the vendor-neutral standard for instrumentation (traces, metrics, logs) and the W3C Trace Context header standardises propagation.
- Propagate the id through every hop, including message queues (put it in message headers).
- Add useful attributes (user type, order size) but never secrets or personal data.
- Sampling: keep all errors and slow traces, a small share of the rest.
Centralised logging
Logs written on many short-lived instances are useless unless shipped to one searchable place.
- Write structured logs (JSON with fields: time, level, service, trace id, message, key attributes) to standard output; let the platform collect them.
- Ship to a central system (the ELK/OpenSearch stack, Loki, Splunk, cloud logging).
- Always include the trace id so logs and traces connect.
- Set levels sensibly; avoid logging personal data and secrets; set retention by value and legal need.
- Alert on log-derived signals sparingly; prefer metrics for alerting.
Health checks
Expose liveness (the process is alive; restart if not), readiness (ready to take traffic; remove from rotation if not) and optionally startup endpoints. Readiness should check what the service truly needs without cascading (a failing optional dependency should degrade, not mark the service unready for everyone).
A minimum for every service
A health endpoint, structured logs with trace ids, the standard metrics (request rate, errors, latency, saturation), propagated trace headers, config and secrets from the environment, and a runbook. The next lesson turns these signals into targets and alerts.
Real-world reading
Related reading
- Feature Toggles (aka Feature Flags)Pete Hodgson · Martin FowlerBlogs
- DevOps Roadmaproadmap.sh community · roadmap.shCourses
- Ensuring rollback safety during deploymentsAmazon Builders' Library · Amazon Web ServicesBlogs
- Dapper: a Large-Scale Distributed Systems Tracing Infrastructure (paper)Sigelman et al. · GooglePapers
Show 6 moreShow fewer
- Blue Green DeploymentMartin FowlerBlogs
- The Twelve-Factor AppAdam Wiggins · 12factor.netDocumentation
- XCMetrics: All-in-One Tool for Tracking Xcode Build Metrics at SpotifySpotify engineers · SpotifyCase Studies
- Going faster with continuous deliveryAmazon Builders' Library · Amazon Web ServicesBlogs
- Unicorn: Remediation System at eBayeBay engineers · eBayCase Studies
- Distributed Tracking, Tracing, and MeasuringOreilly engineers · OreillyCase Studies
System Design Foundations · 12 minDesigning for failure: reliabilityTimeouts, retries, circuit breakers, rate limiting and redundancy: how systems stay up when parts of them break.Read here
Failure is normal
At scale something is always broken: a disk, a network link, a deployment, a dependency having a bad day. Reliable systems do not avoid failure, they expect it and contain it.
Two words to keep apart:
- Availability: the fraction of time the system works (99.9% allows about 8.8 hours of downtime a year; 99.99% about 53 minutes).
- Durability: the chance stored data is not lost.
Remove single points of failure
A single point of failure (SPOF) is any component whose failure takes everything down. Hunt for them:
- Run several application servers behind a load balancer.
- Replicate databases and plan failover (lesson 5).
- Spread across availability zones, and for the most critical services, across regions.
- Do not forget the "invisible" ones: the load balancer, DNS, a certificate that expires, a single queue.
100%Figure SDA-FND-10-1 · Removing single points of failure tier by tier · © forcsguy.com
Protect calls between services
Most outages spread through calls between components. Four basic defences:
1. Timeouts
Every network call needs a timeout. Without it a slow dependency holds your threads hostage. Set timeouts based on what a healthy call looks like (for example a little above the 99th percentile), and make inner timeouts shorter than outer ones.
2. Retries, carefully
Transient errors often succeed on a second try. But retries multiply load on a struggling service, so:
- Retry only idempotent operations or those with an idempotency key (lesson 8).
- Use exponential backoff with jitter.
- Cap the number of attempts, and ideally cap the share of traffic that can be retries.
3. Circuit breakers
If a dependency keeps failing, stop calling it for a short time and fail fast.
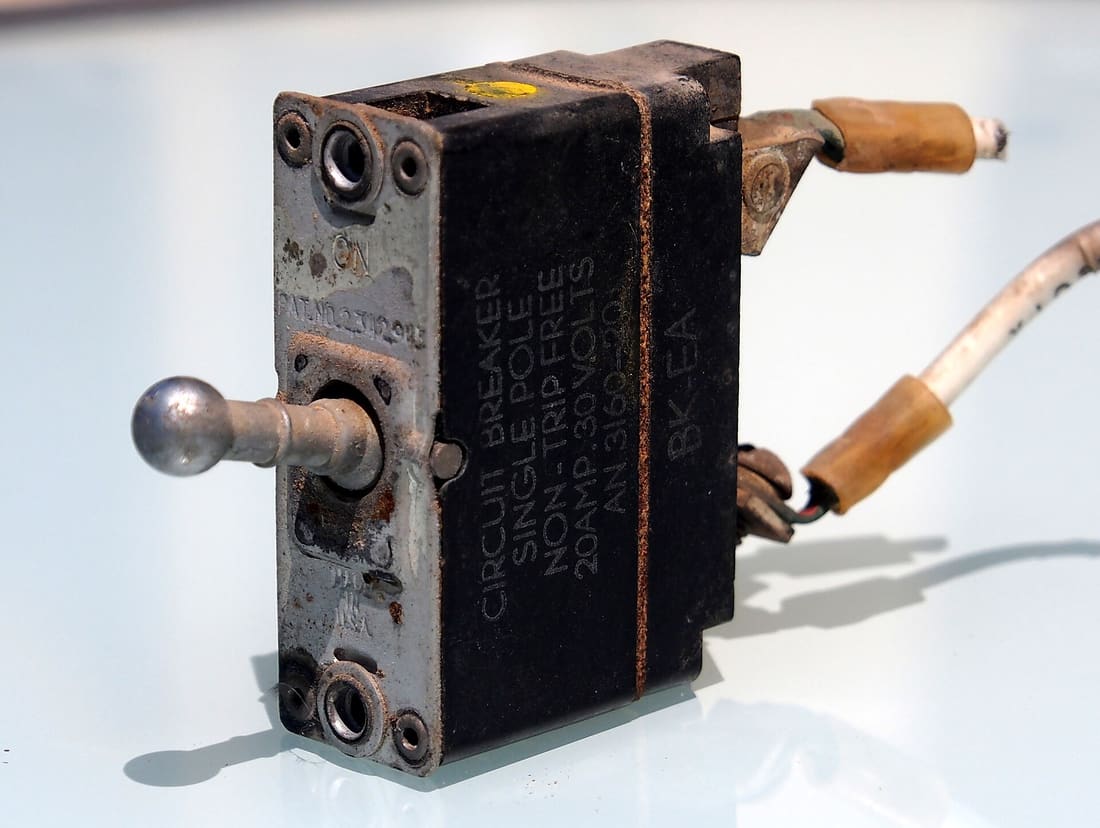 Image: Alf van Beem · CC0 · Source · Wikimedia Commons: Circuit breaker, Single pole, Non-tripfree, 20Amp-30Volts, AN 3160 pic1100%
Figure SDA-FND-10-2 · Circuit breaker states · © forcsguy.com
- Closed: normal operation, failures are counted.
- Open: calls fail immediately, saving resources.
- Half-open: a few trial calls check whether the dependency has recovered.
4. Bulkheads
Give each dependency its own pool of threads or connections, like watertight compartments in a ship, so one slow dependency cannot use up everything.
Before: a slow dependency drags everyone down
100%After: a breaker cuts the slow dependency off
100%What changed
- Callers stop waiting on a failing service
- Threads and connections are not used up
- A fallback answer is returned while the service recovers
Protect yourself from too much traffic
- Rate limiting caps how many requests a client may make (common algorithms: token bucket, sliding window). It protects against abuse and accidental floods.
- Load shedding: when overloaded, deliberately reject low-priority work early so important requests still succeed. It is better to serve 80% of requests well than 100% badly.
- Back pressure: tell producers to slow down instead of letting queues grow without bound.
Degrade gracefully
When a non-critical part fails, keep the rest working: show the page without recommendations, serve cached prices, queue the email. Decide in advance which features are essential.
Practise failure
- Health checks so traffic leaves broken instances.
- Chaos testing: deliberately kill instances in a controlled way to prove the system copes.
- Runbooks and game days so people have rehearsed the response.
A worked example: the arithmetic of availability
Downtime in a month. 99% allows about 7.3 hours; 99.9% about 43 minutes; 99.99% about 4.4 minutes; 99.999% about 26 seconds. Each extra nine is ten times harder and usually much more expensive, so choose the target your users need, not the biggest number.
Dependencies in series multiply. If a request needs three services, each 99.9% available, the request is available only 0.999 x 0.999 x 0.999 = 99.7%, about 2 hours 11 minutes of downtime a month. The more things in the critical path, the worse it gets, which is why teams shorten the critical path and make non-essential calls optional.
Redundancy in parallel helps. Two independent replicas, each 99% available, are both down only 1% x 1% = 0.01% of the time: 99.99% together. The word "independent" carries all the weight: replicas that share a rack, a deploy, a bug or a dependency fail together, and the formula no longer applies.
Retries multiply load. If every one of 1,000 requests per second fails and each caller retries 3 times, the failing service sees up to 4,000 requests per second, making recovery harder. And if three layers each retry 3 times, one user request can become 64 attempts at the bottom. Retries need limits, backoff with jitter, and a retry budget (for example, retries may be at most 10% of normal traffic).
100%Figure SDA-FND-10-3 · How availability combines · © forcsguy.com
Anatomy of a cascading failure
The classic outage is rarely one failure; it is one failure that spreads.
- A database gets slow (a bad query, a noisy neighbour). Responses that took 10 ms now take 5 seconds.
- App servers wait on it. Each request holds a thread for 5 seconds, so threads and connections fill up.
- The app can no longer accept new requests, even ones that do not need the database. The load balancer sees timeouts and marks servers unhealthy, so the same traffic lands on fewer servers.
- Callers time out and retry, which adds load to the already struggling system.
- Everything is down, and fixing the original slow query no longer brings it back, because the retry storm keeps it overloaded.
The defences are cheap compared with the outage:
- Timeouts on every call, shorter than the caller's own timeout.
- Circuit breakers that stop calling a failing dependency for a while and fail fast.
- Bulkheads: separate thread or connection pools per dependency, so one slow one cannot use all of them.
- Load shedding: when overloaded, reject some requests early to keep serving the rest.
- Backoff with jitter and retry budgets.
100%Figure SDA-FND-10-4 · A circuit breaker protects both sides · © forcsguy.com
Mistakes people make
- No timeouts, or timeouts longer than the caller's. The default in many libraries is "wait forever" or minutes.
- Retrying everything everywhere. Retry only safe, idempotent operations, at one layer, with backoff, jitter and a budget.
- Health checks that lie. A server that answers
/healthbut cannot reach its database should fail the check. - Untested failover. Failover that has never run is a guess. Practise it on purpose, in business hours.
- Shared fate. Two "redundant" systems in one zone, on one deploy pipeline, or on one dependency are one system.
- No graceful degradation. Decide in advance which features can be switched off (recommendations, images, analytics) to protect the critical path.
Try it yourself
In the System Builder, lose three servers at peak and find how much spare capacity you need. Read the resilience patterns lesson for circuit breakers and bulkheads in more depth, and build the lease leader election lab to see failover without split brain.
More on this site
Related reading
- Timeouts, retries, and backoff with jitterAmazon Builders' Library · Amazon Web ServicesBlogs
- Using load shedding to avoid overloadAmazon Builders' Library · Amazon Web ServicesBlogs
- Maglev: A Fast and Reliable Software Network Load Balancer (paper)Eisenbud et al. · GooglePapers
- Designing robust and predictable APIs with idempotencyBrandur Leach · StripeBlogs
Show 6 moreShow fewer
- Circuit BreakerMartin FowlerBlogs
- Circuit Breaker patternMicrosoft · Microsoft AzureDocumentation
- Google SRE Book: Addressing Cascading FailuresGoogle SRE team · GoogleBlogs
- Google SRE Book: Handling OverloadGoogle SRE team · GoogleBlogs
- Testing for Disaster Recovery Failover TestingUSENIX engineers · USENIXCase Studies
- Improved Production Stability with Circuit Breakers at HerokuHeroku engineers · HerokuCase Studies
Go deeper on this
A path through videos, articles, other case studies and code on the same ideas as Amazon Builders' Library.
Warm upGet the vocabulary first.
Courses
Google SRE Book
Free online book on running reliable production systems at Google scale.
GoogleAdvanced
Books · Free from the author
The Architecture of Open Source Applications
Chapters by the creators of real open-source systems explaining their architecture; free to read.
aosabook.orgIntermediate
WatchHow others solve the same problem, on video.
Videos belong to their creators and play from YouTube. More on YouTube (opens in a new tab)
ReadEngineers explain it in their own words.
Blogs
Netflix Technology Blog
Engineering posts on resilience, streaming, data and chaos engineering at Netflix.
NetflixAdvanced
Blogs
InfoQ Architecture & Design
News, articles and talks on software architecture and design.
InfoQIntermediate
See it in another companyThe same ideas, a different system.
Case Studies · Read here
GRIT: Protocol for Distributed Transactions across Microservices at eBay
eBay technologists recently showed off a distributed transaction protocol called GRIT, for distributed ACID (atomicity, consistency, isolation, durability) transactions across microservices with multiple underlying da...
eBayAdvanced
Case Studies · Read here
How we built rate limiting capable of scaling to millions of domains
A sliding-window counter running at the edge, with measurements of how accurate the approximation is.
CloudflareAdvanced
Read the codeSee how it looks when it is real.
GitHub
Engineering Blogs
A huge directory of company engineering blogs to learn from real production systems.
kilimchoiIntermediate
GitHub
Awesome Distributed Systems
A curated list of distributed-systems papers, books, talks and courses.
GitHubAdvanced
Keep learning
Loading community…