Library / Blogs
Monolith First
The argument for starting as a monolith and splitting into services once the boundaries are understood.
By Martin Fowler · Martin Fowler · Added 2026-10-12
All content belongs to Martin Fowler. We only link to it and give credit. Report a problem
Learn this article
About 37 min left. Your work is saved as you go.
What you are about to study
Martin Fowler wrote this to explain how they thought about a problem. You can follow it without prior background.
Ideas you will meet
- Microservices
- Decompose systems into independently deployable services.
What we already know about this
Our own lessons on these ideas. Read them here before you start, so it makes sense.
Real-World Systems · 11 minHow microservices work togetherSynchronous calls, events, sagas and discovery: how separate services cooperate without becoming one tangled system.Read here
What a microservice architecture is
Instead of one large application, the system is split into small services, each responsible for one business capability (orders, payments, inventory, users). Services are deployed and scaled independently, often by different teams, and talk over the network.
The benefits are independent deployment, team autonomy and targeted scaling. The cost is that everything that used to be a function call is now a network call that can be slow or fail, and data is spread across services.
Ways services talk
Style How Good for Cost Synchronous request and response (REST, gRPC) Caller waits for the answer Queries and steps the user waits for Coupling in time; failures propagate Asynchronous messages and events (queues, streams) Caller publishes and moves on Reactions, workflows, decoupling Eventual consistency; harder to trace 100%Figure SDA-RWS-13-1 · Services: sync calls, events and owned data · © forcsguy.com
100%Figure SDA-RWS-13-2 · Two ways to run a multi-step process · © forcsguy.com
Before: a chain of synchronous calls
100%After: events between services
100%What changed
- A slow service no longer blocks the order
- New services can listen without changing the sender
- The result is eventually consistent, so design for that
Data ownership
Each service owns its own data and exposes it only through its API or events. No other service reads its tables. This keeps boundaries real, but it means you cannot join across services in SQL: you call APIs or keep read models built from events.
Keeping things consistent: sagas
A business action often spans services (take payment, reserve stock, create shipment). A single database transaction cannot cover them. A saga is a sequence of local transactions, each with a compensating action:
- Create the order (pending).
- Reserve stock. Compensation: release stock.
- Charge the payment. Compensation: refund.
- Confirm the order. If any step fails, run the compensations for earlier steps in reverse.
Two ways to run a saga:
- Choreography: services react to each other's events. Simple and decoupled, but the overall flow is spread out and hard to see.
- Orchestration: a coordinator (an orchestrator service or workflow engine) tells each service what to do next and handles failures. The flow is explicit and easier to reason about.
The outbox pattern
A service must update its database and publish an event, and one may succeed without the other. Write the event to an outbox table in the same transaction, and let a separate process publish it. Consumers must be idempotent, because delivery is at least once.
Finding and reaching services
- Service discovery (via the platform, DNS or a registry) tells callers where healthy instances are, since addresses change constantly.
- An API gateway is the front door for external clients: routing, authentication, rate limiting. A backend for frontend shapes responses for a specific client.
- A service mesh adds a sidecar proxy next to each service to provide mutual TLS, retries, timeouts and metrics without changing application code.
Resilience between services
Reuse the reliability tools: timeouts, retries with backoff and jitter, circuit breakers and bulkheads. Prefer asynchronous communication where a user does not need an immediate answer.
Operating many services
- Distributed tracing with a correlation id shows a request's path across services.
- Contract testing and careful API versioning let teams change without breaking each other.
- Beware the distributed monolith: services so entangled they must be deployed together, which gives you all the costs and none of the benefits. Split along business boundaries, not technical layers.
- Start with a well-structured monolith if the team is small. Split when a real need appears.
More on this site
Related reading
- Pattern: Transactional outboxChris Richardson · microservices.ioDocumentation
- Pattern: SagaChris Richardson · microservices.ioDocumentation
- Awesome MicroservicesMehdi Fornos · mfornosGitHub
- Microservices PatternsChris Richardson · ManningBooks
Show 6 moreShow fewer
- Tech Dummies: System Design Case StudiesNarendra L · Tech DummiesYouTube
- Payment Transaction Management in Microservices at MercariMercari engineers · MercariCase Studies
- Circuit BreakerMartin FowlerBlogs
- Avoiding insurmountable queue backlogsAmazon Builders' Library · Amazon Web ServicesBlogs
- Microservice Architecture at MediumMedium engineers · MediumCase Studies
- Back-end at FlickrFlickr engineers · FlickrCase Studies
Messaging and Microservice Patterns · 13 minOperating microservices: config, secrets, feature flags, tracing and loggingThe operational toolkit around a service: configuration and secrets done safely, feature flags for controlled releases, and traces and logs that follow a request across services.Read here
Configuration
Separate configuration from code. Anything that changes between environments (database address, feature limits, endpoints) should come from environment variables, config files or a config service, not be baked into the build ("build once, run anywhere").
- Keep defaults in code and overrides in the environment.
- Validate configuration at start-up and fail fast with a clear message.
- For values that must change at runtime, use a config service or watch a mounted file, and treat changes like deployments (versioned, reviewed, auditable).
- Keep config in version control (as code or templates) so changes are reviewed and reversible.
Secrets
Secrets (passwords, API keys, private keys, tokens) need stricter handling.
- Never commit them, put them in images, or print them in logs.
- Store them in a secrets manager (a cloud service, HashiCorp Vault, or an encrypted platform secret store) with access control, audit logs and encryption at rest.
- Inject at runtime (environment, mounted file or an agent), and use short-lived credentials where possible (cloud roles, dynamic database credentials).
- Rotate regularly and after any suspected leak; design services to reload secrets without downtime.
- Least privilege: each service gets only its own secrets.
Feature flags
A feature flag is a runtime switch controlling whether code runs, separate from deployment.
100%Figure SDA-MSV-05-1 · Deploy is not release · © forcsguy.com
Uses: gradual rollout, kill switches for risky features, A/B tests, per-customer entitlements, and decoupling release from deploy (see the deployment strategies lesson). Cautions: flags multiply test combinations, can be left in place forever, and a flag service outage must fail to a safe default.
Distributed tracing
A request through a microservice system touches many services. A trace records the whole journey as a tree of spans (one per operation), joined by a trace id passed in request headers.
100%Figure SDA-MSV-05-2 · One request traced across services · © forcsguy.com
- OpenTelemetry is the vendor-neutral standard for instrumentation (traces, metrics, logs) and the W3C Trace Context header standardises propagation.
- Propagate the id through every hop, including message queues (put it in message headers).
- Add useful attributes (user type, order size) but never secrets or personal data.
- Sampling: keep all errors and slow traces, a small share of the rest.
Centralised logging
Logs written on many short-lived instances are useless unless shipped to one searchable place.
- Write structured logs (JSON with fields: time, level, service, trace id, message, key attributes) to standard output; let the platform collect them.
- Ship to a central system (the ELK/OpenSearch stack, Loki, Splunk, cloud logging).
- Always include the trace id so logs and traces connect.
- Set levels sensibly; avoid logging personal data and secrets; set retention by value and legal need.
- Alert on log-derived signals sparingly; prefer metrics for alerting.
Health checks
Expose liveness (the process is alive; restart if not), readiness (ready to take traffic; remove from rotation if not) and optionally startup endpoints. Readiness should check what the service truly needs without cascading (a failing optional dependency should degrade, not mark the service unready for everyone).
A minimum for every service
A health endpoint, structured logs with trace ids, the standard metrics (request rate, errors, latency, saturation), propagated trace headers, config and secrets from the environment, and a runbook. The next lesson turns these signals into targets and alerts.
Real-world reading
Related reading
- Feature Toggles (aka Feature Flags)Pete Hodgson · Martin FowlerBlogs
- DevOps Roadmaproadmap.sh community · roadmap.shCourses
- Ensuring rollback safety during deploymentsAmazon Builders' Library · Amazon Web ServicesBlogs
- Dapper: a Large-Scale Distributed Systems Tracing Infrastructure (paper)Sigelman et al. · GooglePapers
Show 6 moreShow fewer
- Blue Green DeploymentMartin FowlerBlogs
- The Twelve-Factor AppAdam Wiggins · 12factor.netDocumentation
- XCMetrics: All-in-One Tool for Tracking Xcode Build Metrics at SpotifySpotify engineers · SpotifyCase Studies
- Going faster with continuous deliveryAmazon Builders' Library · Amazon Web ServicesBlogs
- Unicorn: Remediation System at eBayeBay engineers · eBayCase Studies
- Distributed Tracking, Tracing, and MeasuringOreilly engineers · OreillyCase Studies
Real-World Systems · 13 minDesign a stock exchangeAn order book, a matching engine and a sequencer: how an exchange matches buyers and sellers fairly in microseconds.Read here
The problem
An exchange lets buyers and sellers trade. Participants submit orders; the exchange matches them and reports the trades.
Key properties:
- Fairness: orders are handled in a strict, auditable order.
- Very low latency: microseconds from order to acknowledgment.
- High throughput: hundreds of thousands to millions of orders per second at peaks.
- Correctness and durability: money is involved. No lost or duplicated trades.
- Availability: an exchange outage halts a market.
The order book
For each symbol the order book holds resting orders:
- Bids (buy orders), highest price first.
- Asks (sell orders), lowest price first.
- Within a price level, orders queue by arrival time.
Common order types: limit (a worst price you accept; unmatched part rests in the book) and market (take the best available now).
Matching: price-time priority
An incoming buy matches the lowest-priced asks it can afford; among equal prices the earliest order matches first. Matching repeats until the order is filled or no longer matches, and any remainder rests in the book.
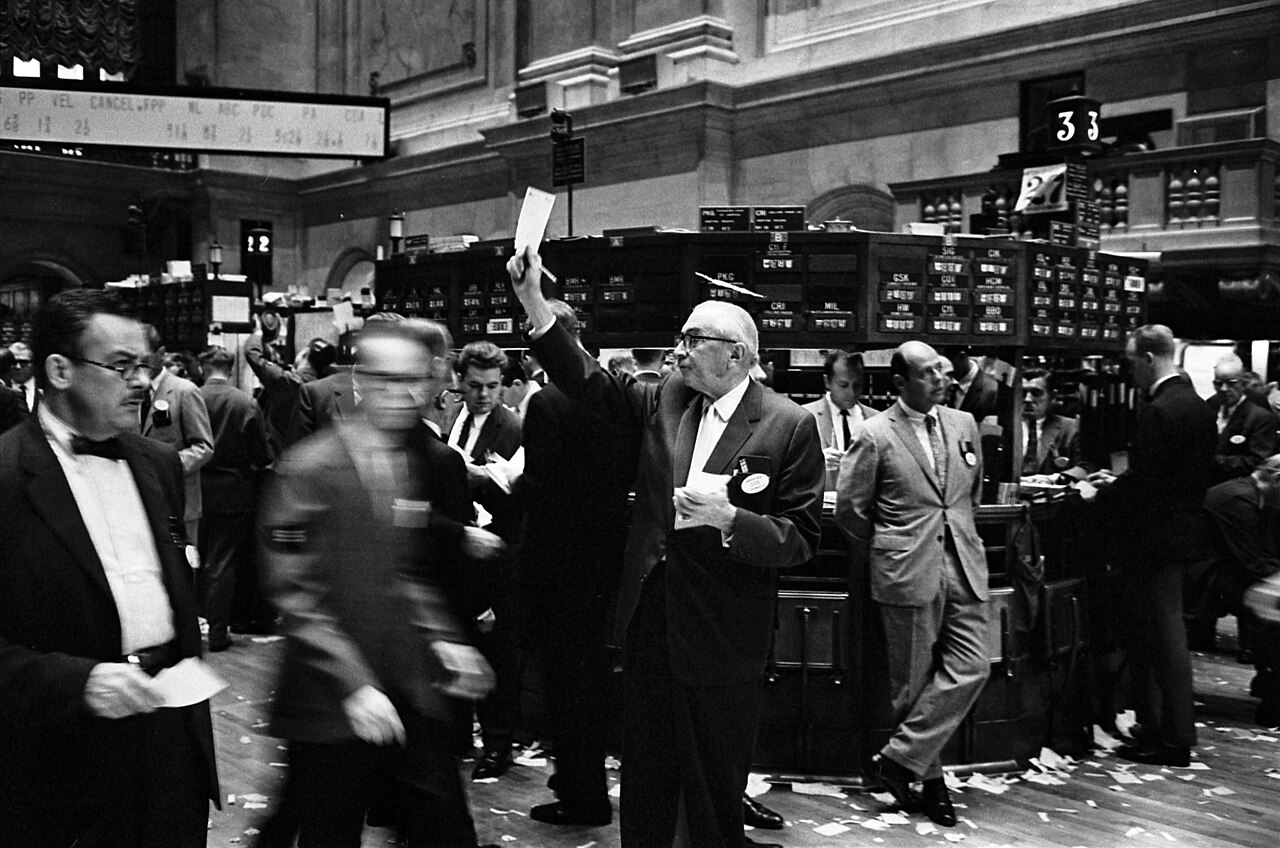 Image: Thomas J. O'Halloran · Public domain · Source · Wikimedia Commons: NY stock exchange traders floor LC-U9-10548-6
Architecture
100%Figure SDA-RWS-05-1 · Exchange: gateway, sequencer, matching engine · © forcsguy.com
- Gateways authenticate participants, validate orders, and run pre-trade risk checks (limits, available funds).
- The sequencer gives every event a sequence number: one agreed total order, the basis of fairness and recovery.
- A matching engine applies events in order to the in-memory order book and emits trades.
- Everything is written to a durable event log. Executions go to participants, and a market data stream tells everyone about prices and depth.
- Clearing and settlement later move money and securities between accounts.
100%Figure SDA-RWS-05-2 · An order book with a buy order sweeping the sell side · © forcsguy.com
How it gets so fast
- In-memory order books and no database in the critical path.
- Single-threaded matching per symbol group: no locks, deterministic behaviour. Parallelism comes from partitioning symbols across engines.
- Event sourcing: state is the result of applying an ordered log. Persist the event first (to a memory-mapped file or replicated log), then process.
- Pre-allocated memory, ring buffers, no garbage-collection pauses, and careful cache-friendly data structures.
- Hardware and network: servers co-located in the exchange's data centre, fast network cards and kernel-bypass networking, precise time sources.
100%Figure SDA-RWS-05-3 · A fast engine on one machine: shared log and busy loops · © forcsguy.com
Reliability
- A hot standby applies the same event log and can take over within moments. Use sequence numbers to detect gaps and avoid duplicate processing.
- Replicate the log across machines or sites before acknowledging, trading a little latency for durability.
- Idempotent order identifiers prevent a resubmitted order executing twice.
- Circuit breakers halt trading when prices move too fast.
Market data fairness
Everyone should see the same information at about the same time. Exchanges publish through multicast feeds, give all participants equal-length cables inside the data centre, and timestamp events at the matching engine. A separate, slower snapshot and retransmission service helps receivers that miss packets.
What is out of scope here
Clearing houses, settlement cycles, regulation and surveillance are large systems of their own. The core design is the sequencer plus deterministic matching engine plus durable log.
Real-world reading
Related reading
- Event SourcingMartin FowlerBlogs
- Monolith FirstMartin FowlerBlogs
- Rewriting the heart of our sync engineDropboxCase Studies
- Cape: Event Stream Processing Framework at DropboxDropbox engineers · DropboxCase Studies
Show 6 moreShow fewer
- Improving Search Engine Efficiency by over 25% at eBayeBay engineers · eBayCase Studies
- Finding Kafka throughput limit in infrastructure at DropboxDropbox engineers · DropboxCase Studies
- Bullet: Forward-Looking Query Engine for Streaming Data at YahooYahoo engineers · YahooCase Studies
- MicroservicesJames Lewis and Martin Fowler · Martin FowlerBlogs
- The LMAX ArchitectureMartin FowlerCase Studies
- Microservices and OrchestrationMartinfowler engineers · MartinfowlerCase Studies
Go deeper on this
A path through videos, articles, other case studies and code on the same ideas as Monolith First.
Warm upGet the vocabulary first.
Documentation
CNCF Cloud Native Landscape
An interactive map of the cloud-native tools, grouped by category.
CNCFBeginner
Documentation
Design Patterns Catalogue
Illustrated explanations of the classic object-oriented design patterns with examples.
Refactoring GuruBeginner
WatchHow others solve the same problem, on video.
Videos belong to their creators and play from YouTube. More on YouTube (opens in a new tab)
ReadEngineers explain it in their own words.
Blogs
Amazon Builders' Library
How Amazon builds reliable systems: timeouts, retries, backoff, load shedding.
Amazon Web ServicesAdvanced
Blogs
Uber Engineering Blog
How Uber builds dispatch, maps, data platforms and real-time infrastructure.
UberAdvanced
See it in another companyThe same ideas, a different system.
Case Studies · Read here
Operate Kubernetes Reliably at Stripe
We recently built a distributed cron job scheduling system on top of Kubernetes, an exciting new platform for container orchestration. Kubernetes is very popular right now and makes a lot of exciting promises: one of ...
StripeIntermediate
Case Studies · Read here
API Platform at Riot Games
Hello all, Leigh Estes, aka RiotSchmick, here. I’m a software engineer at Riot Games working in the Service Availability initiative. Our first article on the API covered our goals, the responsibilities of the Develope...
Riot GamesIntermediate
Read the codeSee how it looks when it is real.
GitHub
System Design (Karan Pratap Singh)
A free, structured system design course in markdown, from IP and DNS to CAP and microservices.
karanpratapsinghBeginner
GitHub
Awesome Microservices
Curated tools, frameworks and reading material for building microservice systems.
mfornosIntermediate
Keep learning
Loading community…